
Embodied Models#
Choose a model or policy class to find its installation, checkpoint, and RL training workflow. For examples organized by benchmark, see RL with Embodied Simulators.
Hardware Support#
NVIDIA is the default backend in the model recipes. AMD ROCm, Huawei Ascend CANN, and Moore Threads MUSA also support the three model families below on LIBERO and ManiSkill. Follow a model link for installation and launch instructions. On non-CUDA backends, ManiSkill runs PhysX on CPU and selects the renderer independently.
Model |
Hardware |
Environment and Scope |
|---|---|---|
LIBERO · ManiSkill |
||
LIBERO · ManiSkill with a |
||
LIBERO · ManiSkill · RoboTwin on ROCm |
Model Recipes#
Open a model page for the full workflow and its supported environments.
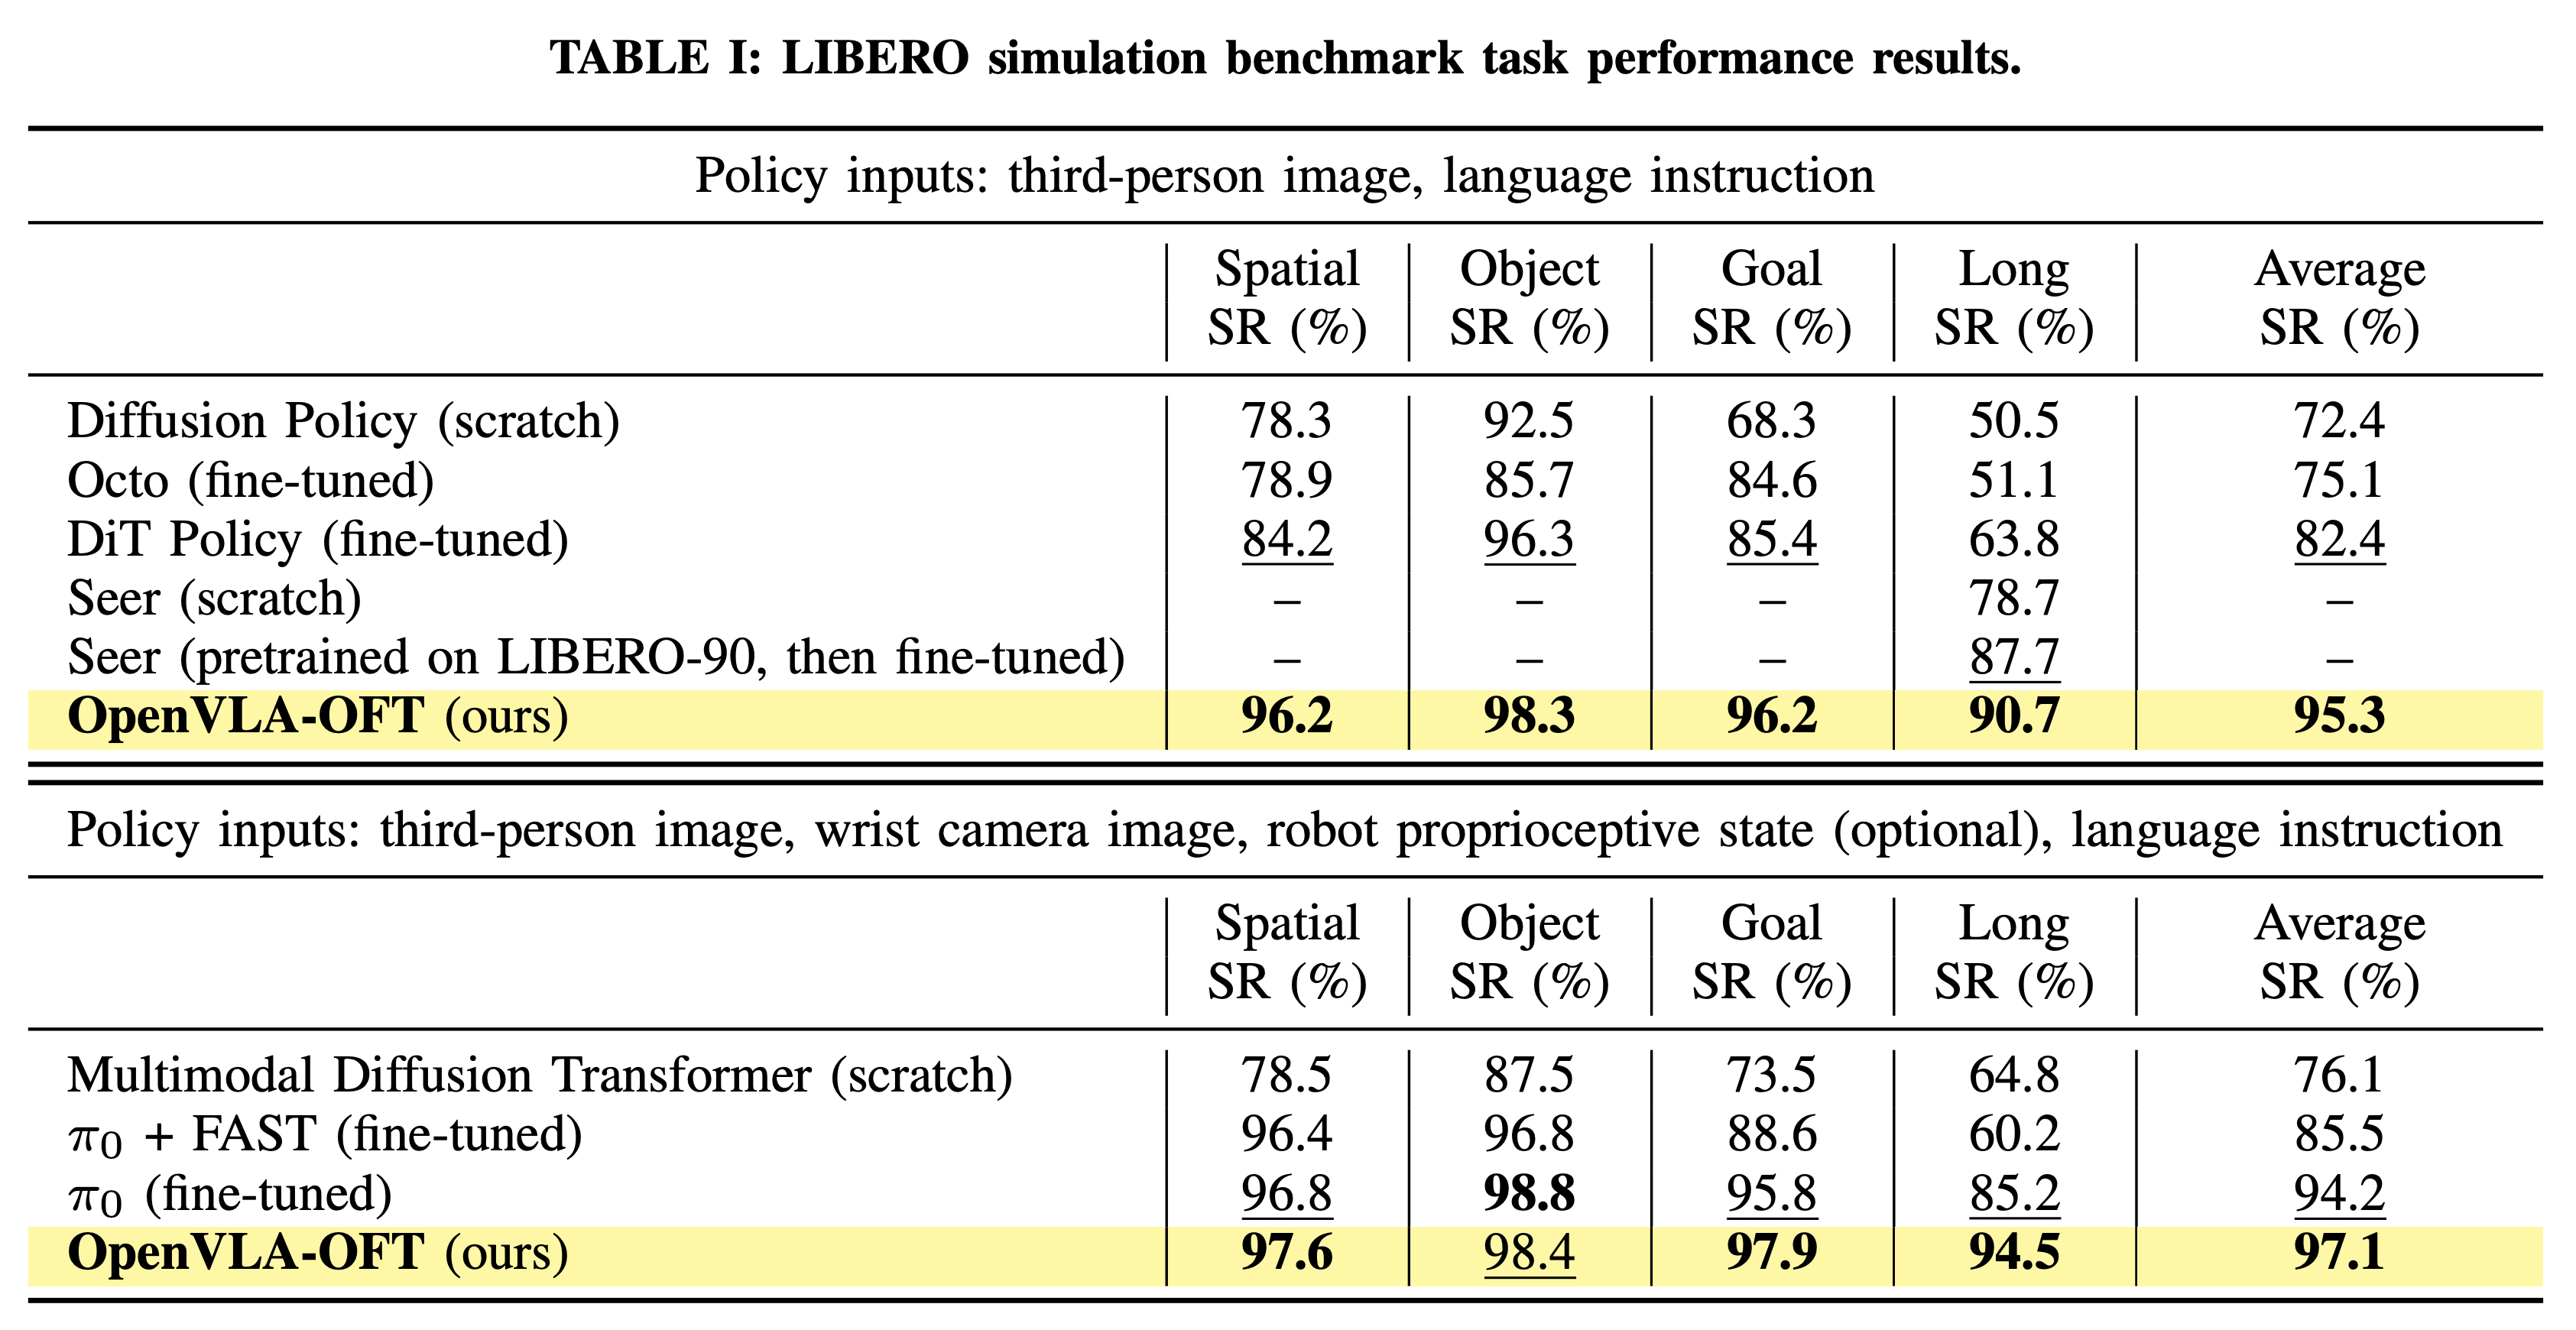
OpenVLA-OFT
LIBERO training on NVIDIA CUDA, AMD ROCm, Huawei Ascend CANN, and Moore Threads MUSA
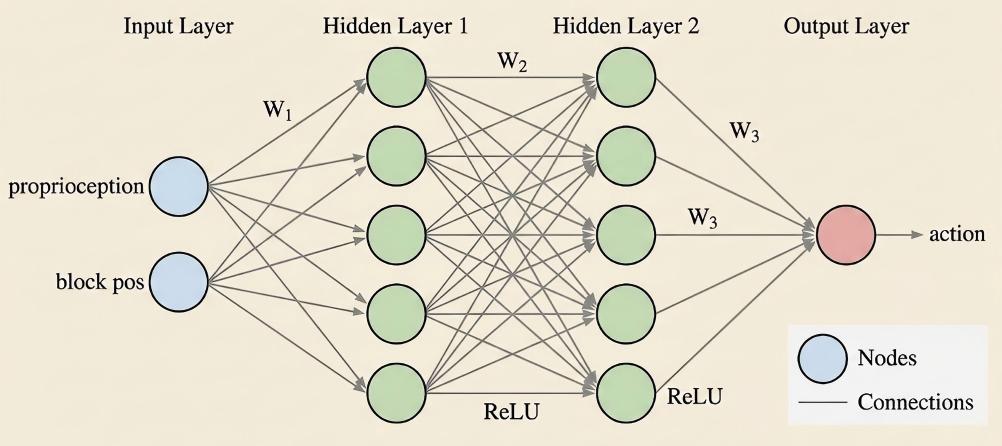
RL on MLP Policy
Train a lightweight MLP policy with PPO, SAC, or GRPO across simulation environments
RL on π₀-FAST
LeRobot π₀-FAST + LIBERO-Long + token-level GRPO
RL on π₀ and π₀.₅ Models
Significant improvement in RL training on π₀ and π₀.₅
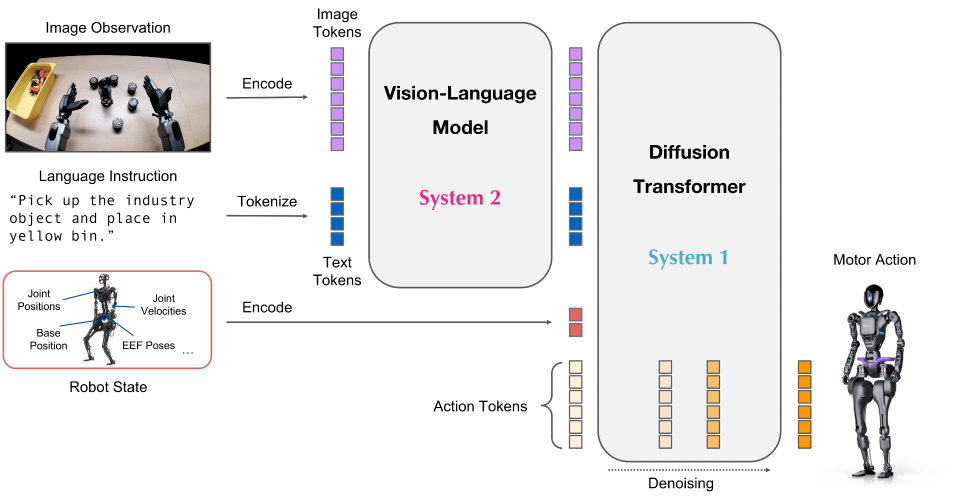
RL on GR00T Models
Support GR00T-N1.5, N1.6 and N1.7 RL fine-tuning.
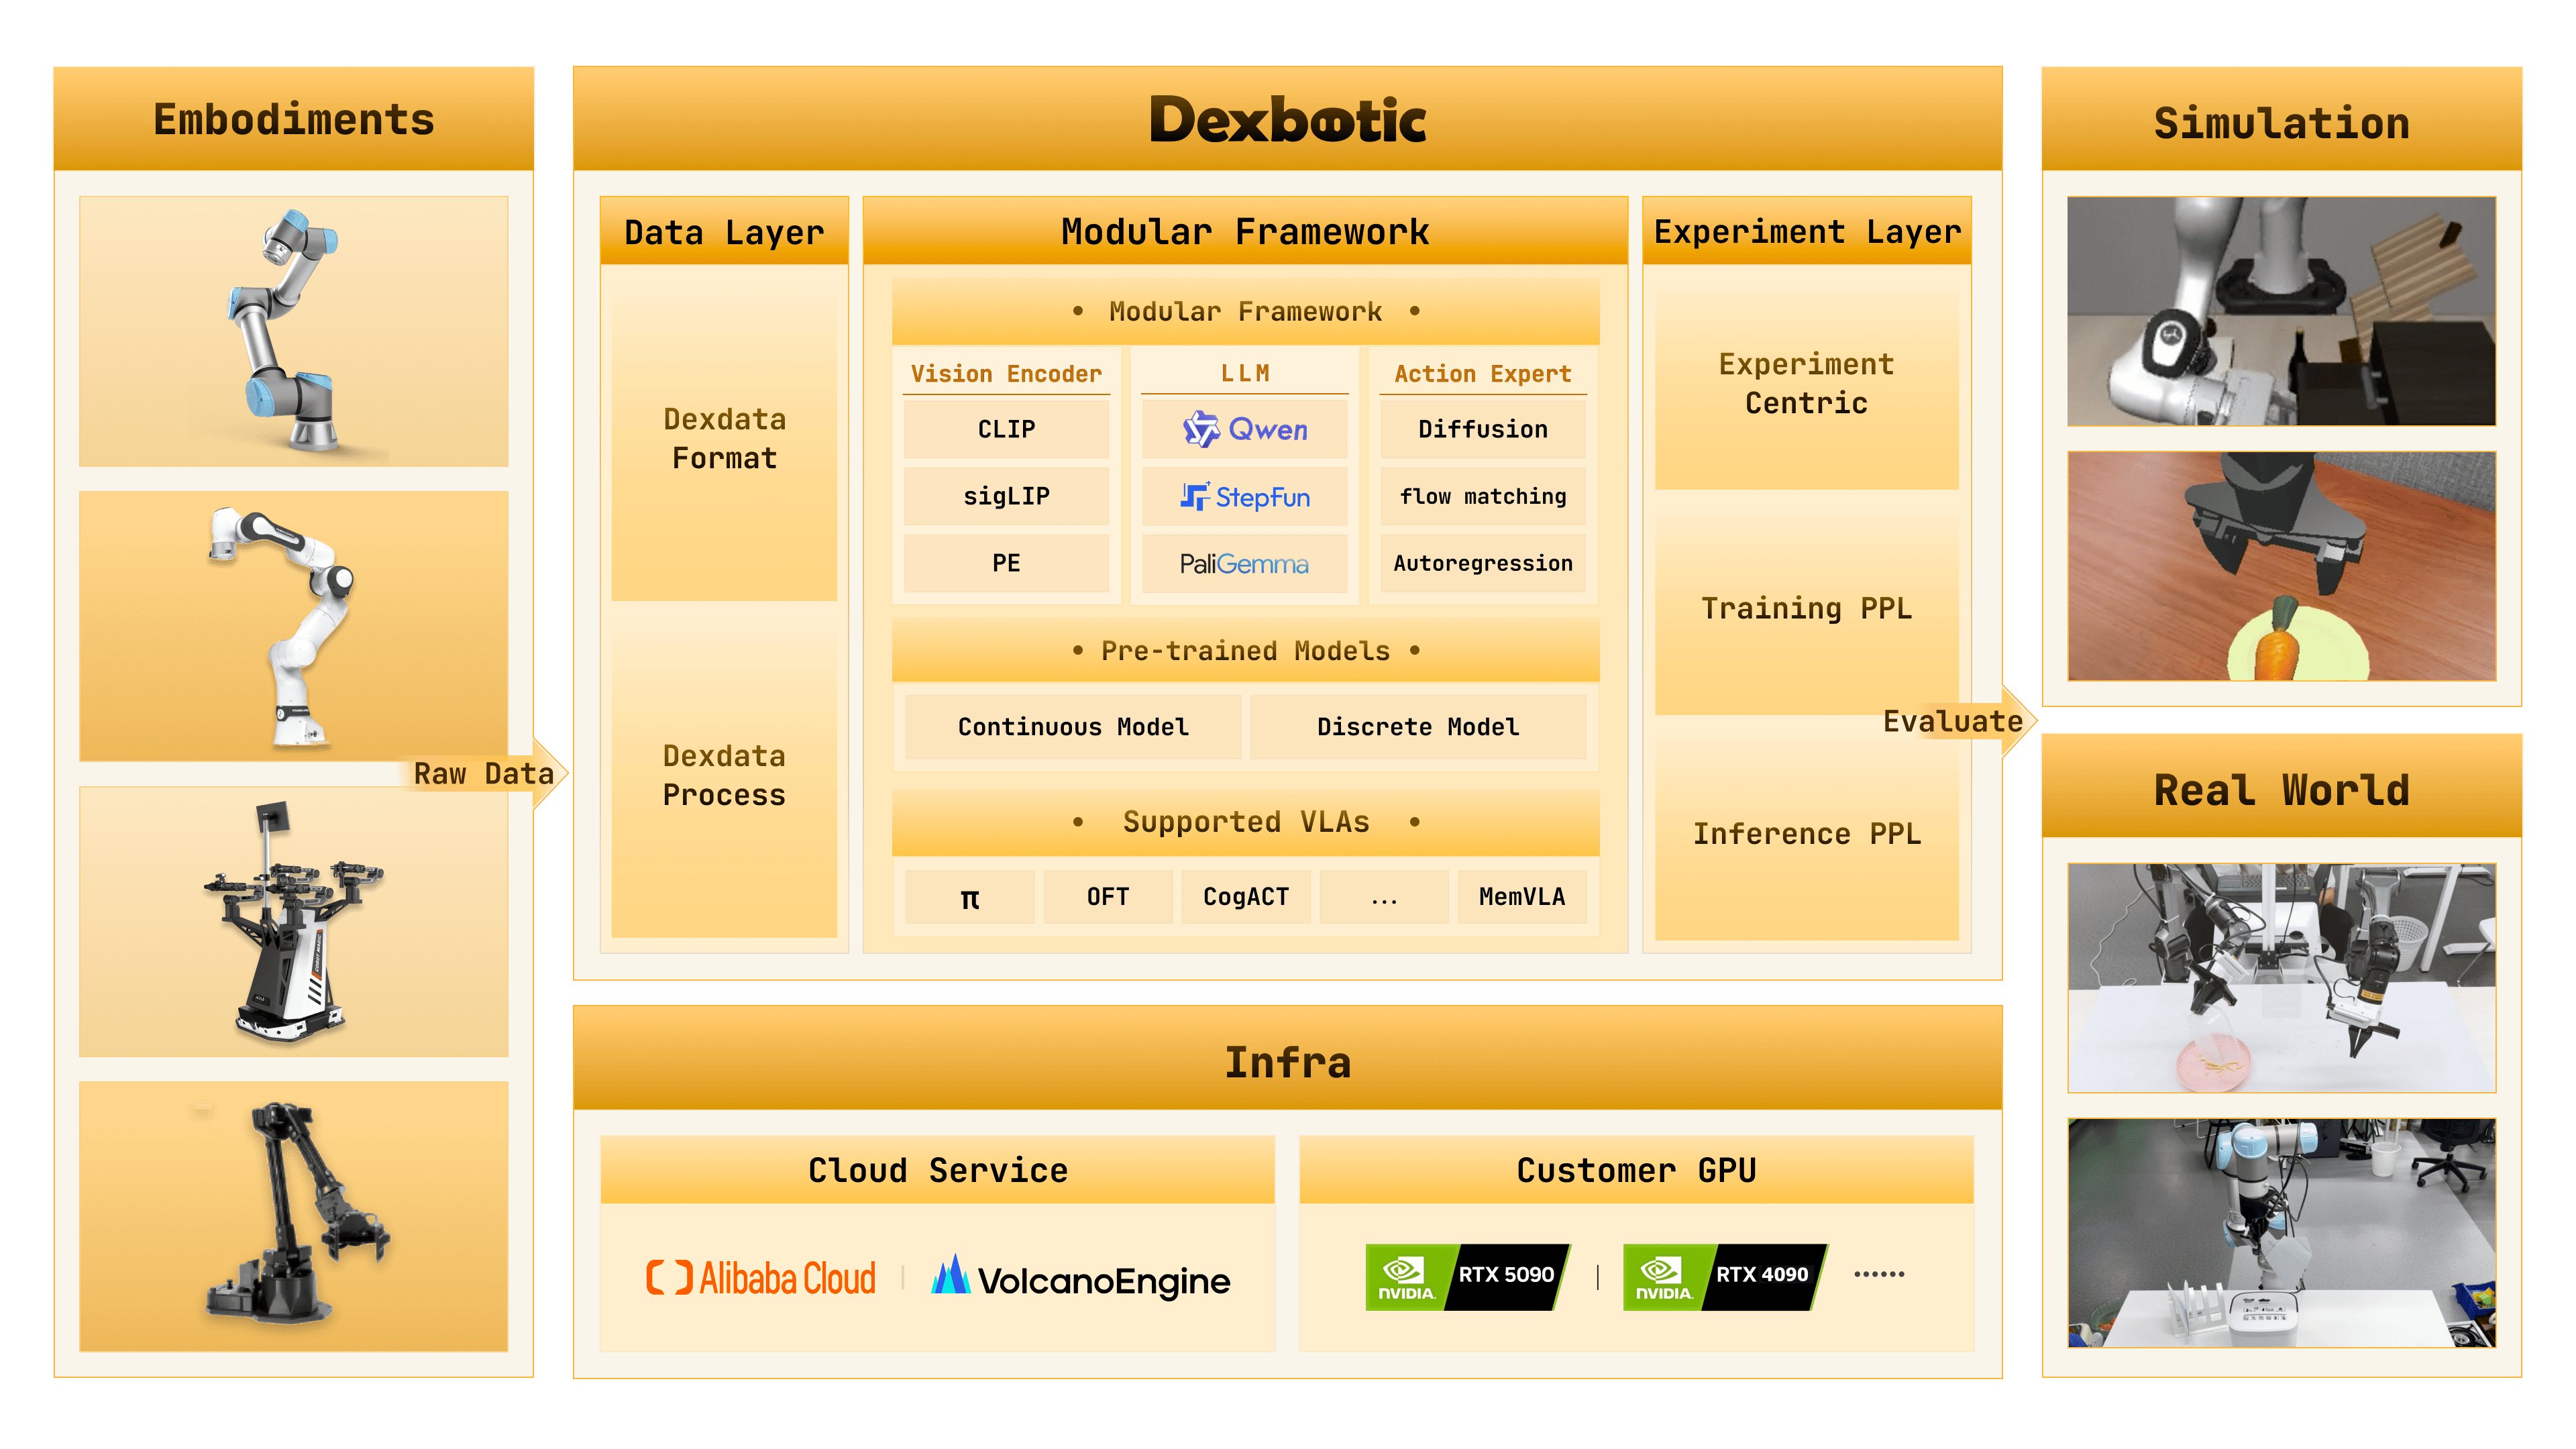
RL on Dexbotic Model
Dexbotic (π₀.₅-based) + LIBERO + PPO training
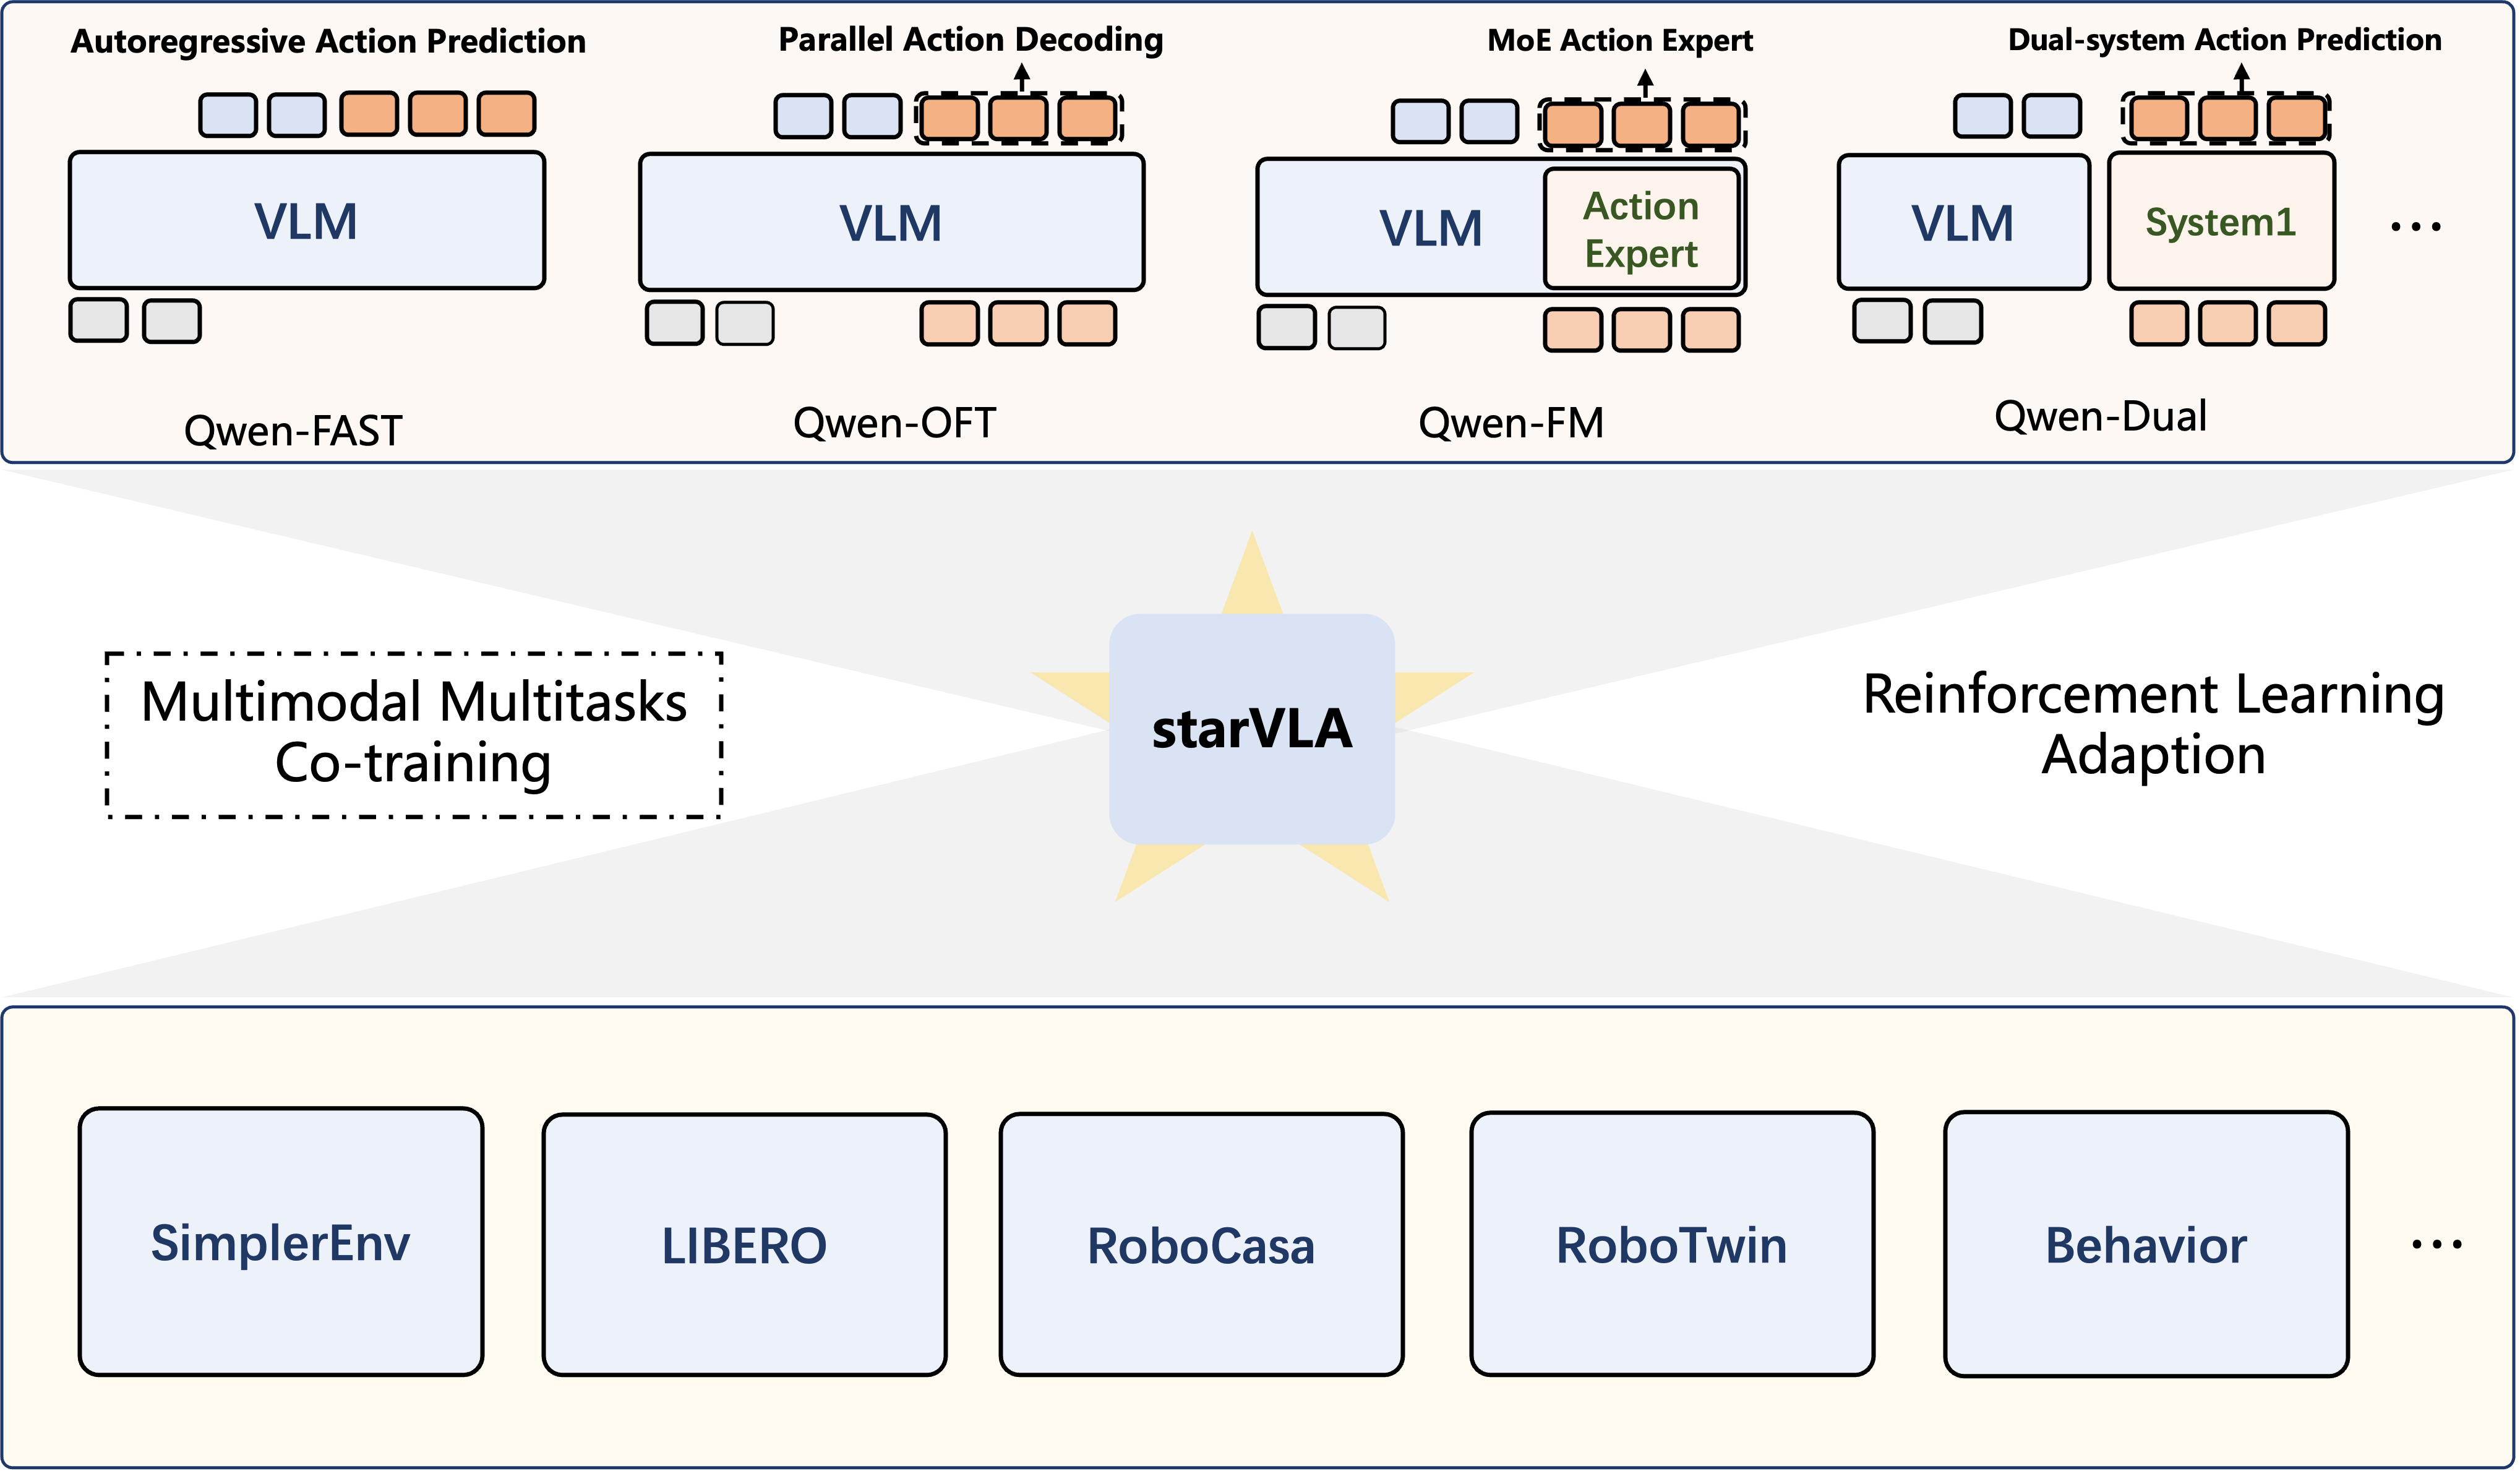
RL on StarVLA Models
StarVLA + LIBERO + GRPO embodied RL training

MolmoAct2 Evaluation
Evaluate the official MolmoAct2-LIBERO checkpoint on LIBERO
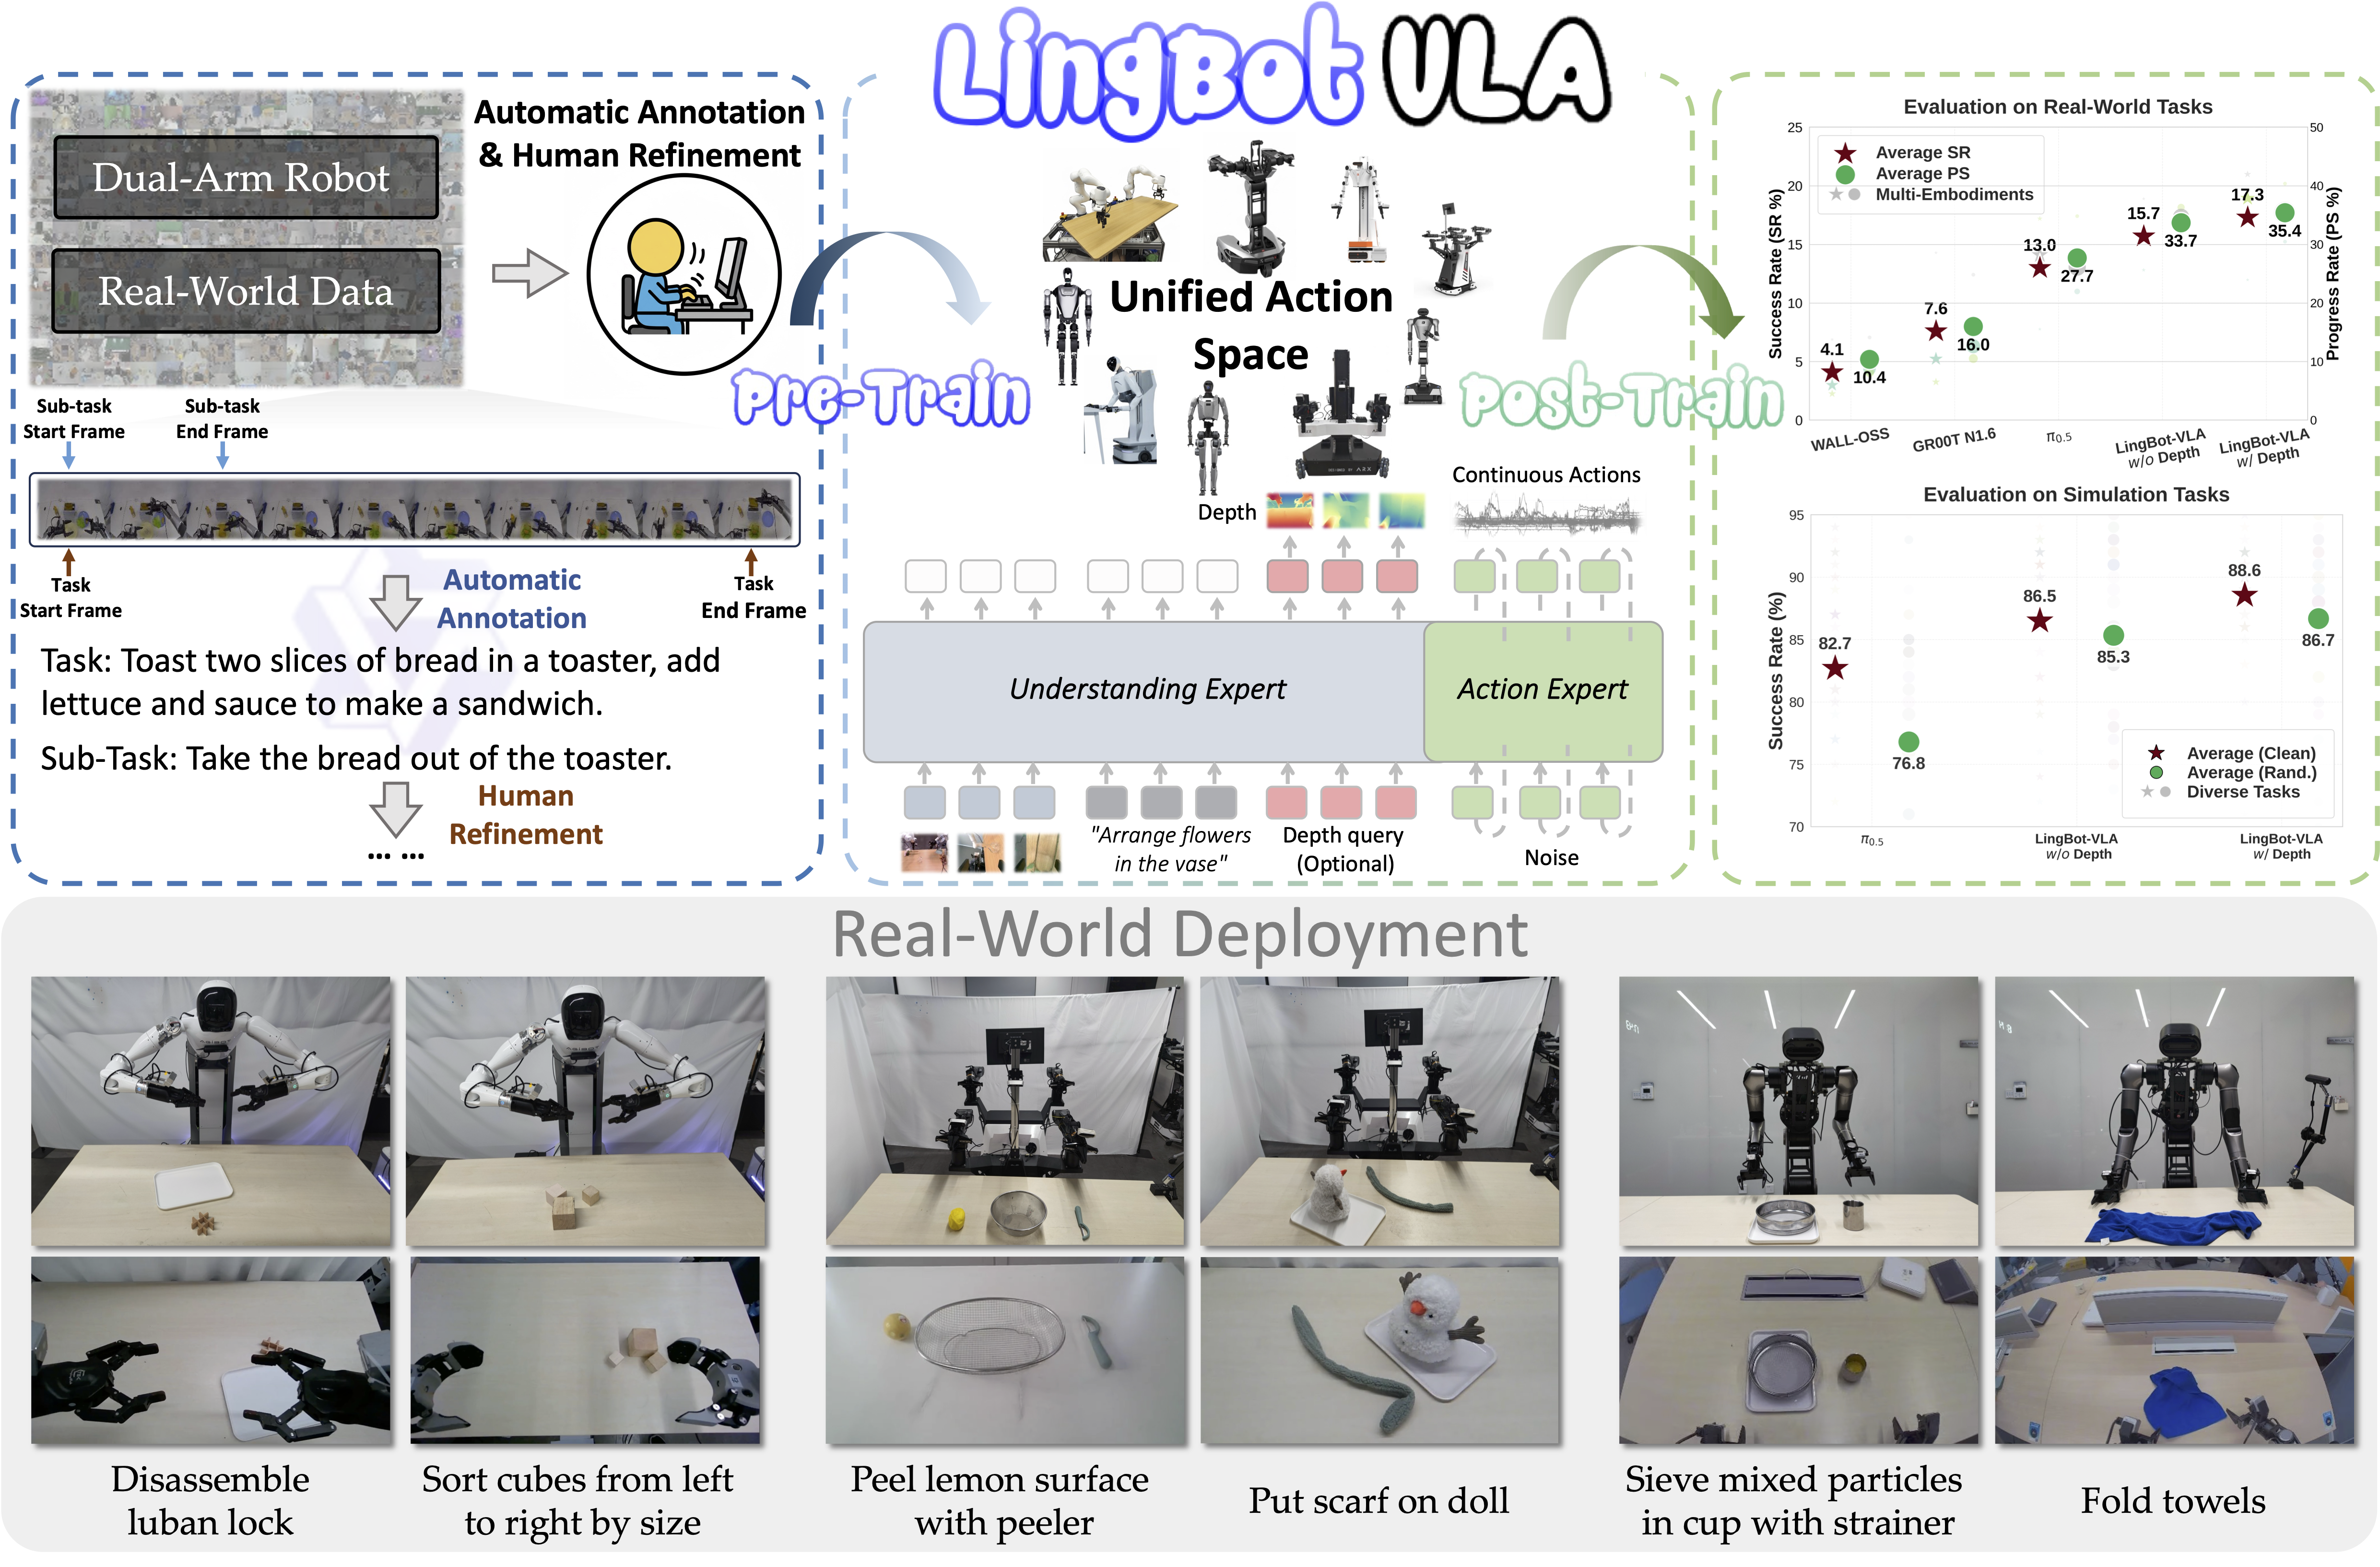
RL with LingbotVLA Models
Support LingbotVLA 1.0 (GRPO) and 2.0 (PPO) + RoboTwin

RL on Evo-1 Models
Train the Evo-1 vision-language-action model with embodied RL
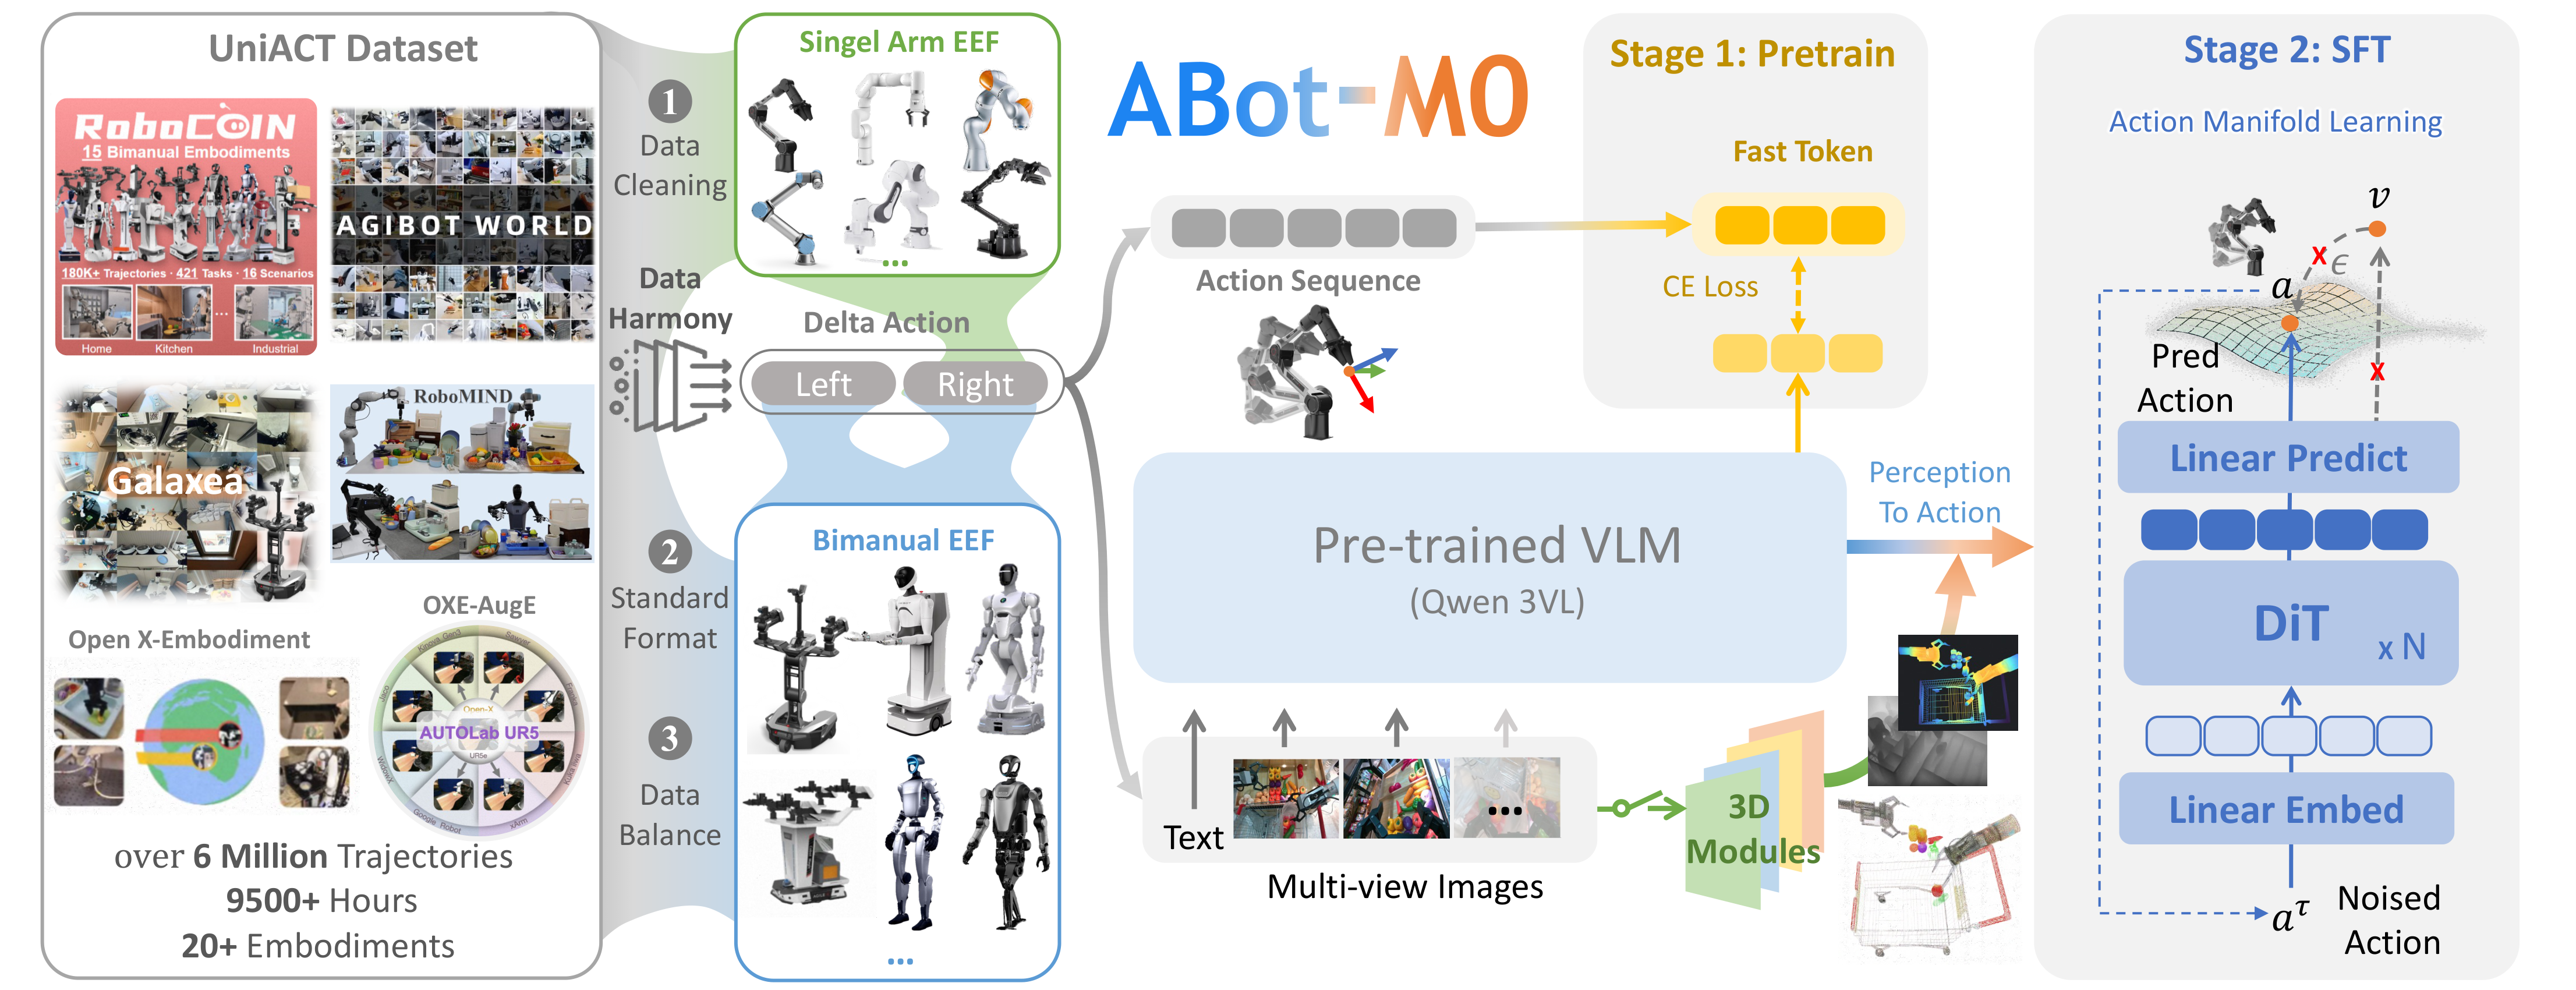
RL on ABot-M0 Model
ABot-M0 native integration with LIBERO-plus PPO training
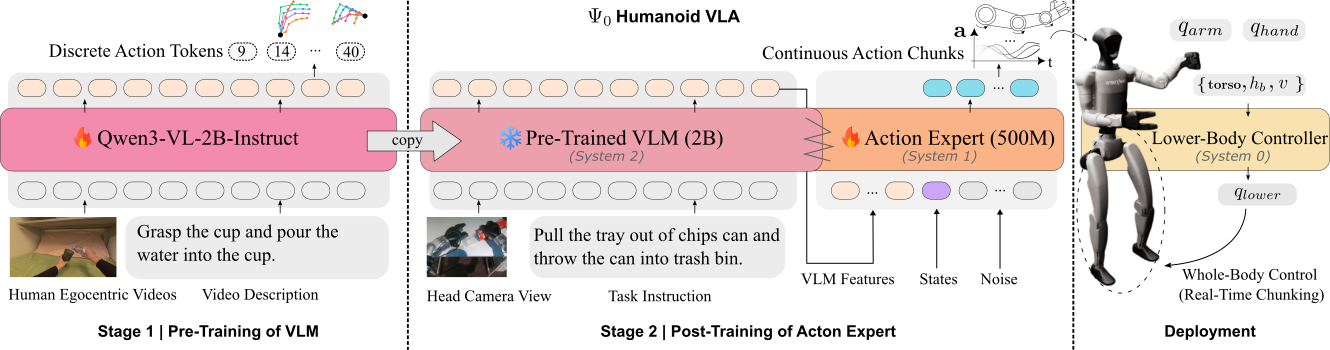
RL on Psi0 Model
Psi0 + SIMPLE + PPO humanoid RL training